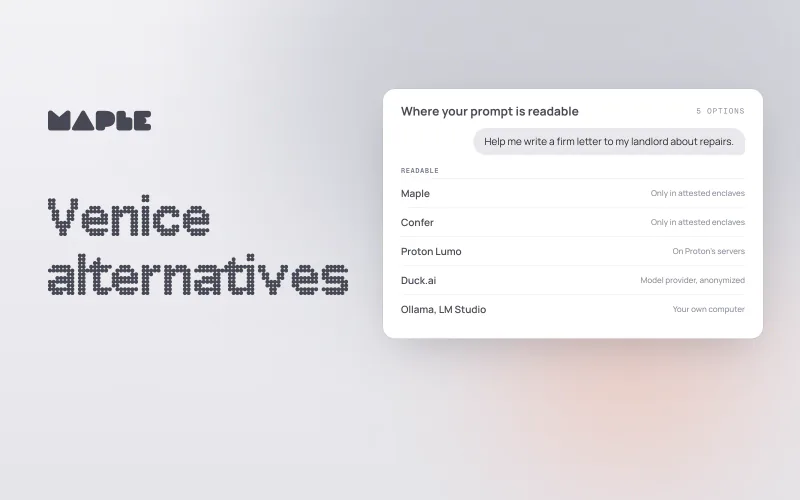
The main Venice AI alternatives are Maple and Confer for privacy you can check, Proton Lumo and Duck.ai for policy-based privacy, and local apps for uncensored models. If you use Venice for privacy, Maple and Confer decrypt every prompt only inside attested enclaves, and their apps check the enclave before sending. Proton Lumo relies on Proton's policy, and Duck.ai on an anonymizing proxy.
If you use Venice for fewer refusals, Maple offers DeepSeek V4.1 Flash Uncensored on paid plans, and you can run abliterated models on your own computer. Venice still leads on model range, media generation and price.
We make Maple. Every claim about another company links to that company's own pages. For a head-to-head, read Maple vs Venice AI. For every private chat app we checked, not only Venice alternatives, see the best private AI chat apps.
Is there anything better than Venice AI?
It depends on what you use Venice for. Most people come for privacy, fewer refusals, or both, and Venice does both in one app with the widest model list here. Each alternative handles one job differently.
For fewer refusals, Venice offers uncensored models on every plan, including Free, and NSFW image generation on Pro.1 Maple has one uncensored text model, on paid plans.
For privacy, the deciding detail is where your prompt is decrypted. An attested enclave is a hardware-isolated part of a server that produces a signed report, called an attestation, showing which code it runs, and it helps only if something checks it before your prompt leaves.
| Product | Where your prompt is decrypted | Who checks it, and when | Text models | Uncensored models |
|---|---|---|---|---|
| Venice | Depends on the mode: the model provider, Venice or partner GPUs, or an enclave2 | The web app checks for E2EE sessions; a verification icon on each E2EE response | About 140 | On every plan, including Free |
| Maple | Only inside attested enclaves, for every chat | The app checks automatically at the start of each session | 8 open-weight (2 on Free) | One, on Pro, Max and Team |
| Confer | Only inside an attested enclave3 | The client checks a public transparency log before sending | Not named | None found |
| Proton Lumo | Proton's GPU servers4 | No attestation found | 3, plus 2 image models | None found |
| Duck.ai | The model provider, without your identity5 | No attestation shown to users | 10, including Claude and GPT | None found |
| Ollama, LM Studio | Your own computer6 | Nothing to check; nothing leaves | Whatever your hardware runs | Community abliterated versions |
Checked 31 Oct 2026. Venice's count is from its public model list.7
Venice also generates images, video and music. Of the alternatives, Lumo and Duck.ai generate images; none generates video.
Why people look for a Venice AI alternative
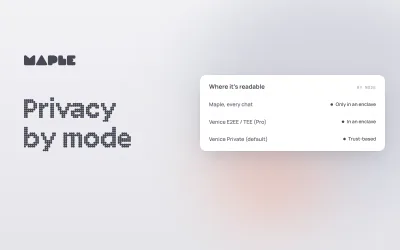
Venice gives each model one of four privacy modes, and the mode decides who handles your prompt in readable form. All four start the same way: every request "passes through the same proxy architecture."2
| Mode | Where it runs | In Venice's words |
|---|---|---|
| Anonymous | Third-party providers such as GPT, Claude and Gemini, through Venice's proxy | "Provider sees and likely saves your prompt" |
| Private (default) | "Venice-controlled GPUs or zero-data-retention partner infrastructure" | "Trust-based — relies on Venice and partners honoring contracts" |
| TEE (Pro) | Partner enclaves run by NEAR AI Cloud and Phala Network, after Venice's proxy | "Neither the partner nor Venice can access your prompts during processing"; "you are still trusting Venice that data in transit is not being retained" |
| E2EE (Pro) | Encrypted in your browser, decrypted only inside the enclave | "no one (including Venice) can see your data" |
Checked 31 Oct 2026, from Venice's privacy page.
Venice's strongest privacy is a paid, per-model choice. TEE and E2EE need Pro and one of 12 open-weight models. In E2EE, your browser encrypts each message to a key bound to the enclave's attestation,8 and Venice's web app checks that enclave for E2EE sessions; a verification icon on each E2EE response opens the attestation report.
To keep that boundary, Venice turns off web search, memory and file uploads in E2EE.9
Outside E2EE, the protection is a promise, and Venice states it plainly. Its privacy page describes the proxy step this way:
Your request passes through Venice's proxy over standard SSL/TLS and is relayed without being stored.
TEE mode shields the prompt from the GPU operator, but Venice's E2EE launch post notes that "you are still trusting Venice that the data in transit is not being retained (it's not)."10
Memory follows the same pattern. Venice's memory feature, Memoria, stores memories in your browser, and Venice says its servers "only generate embeddings transiently. They do not store your memories."11 Web search is off in E2EE because, in Venice's words, it "would require decrypting your prompt outside the enclave."
The difference is policy versus design. Outside E2EE, you rely on Venice's word. That isn't a claim that Venice mishandles anything; it's what you're asked to trust.
What are the private alternatives to Venice AI?
Four hosted apps cover the private side, ordered by how privacy is enforced: attested enclaves by default, then operator policy, then an anonymizing proxy.
Maple
- Where prompts are decrypted: Only inside attested enclaves, on every plan
- Who checks it: The app verifies Maple's enclave at the start of each session, and Maple's enclave verifies the model's
- History and memory: History syncs across devices, encrypted; no cross-chat memory yet
- Platforms: Web, iPhone and iPad, Android, macOS, Windows, Linux, and an API
There's no mode to pick: every model, on every plan, uses the same enclave path, and web search is included on every plan. Details are in What is Maple?
Confer
- Where prompts are decrypted: Only inside an attested enclave
- Who checks it: The client checks the enclave against a public transparency log before sending
- History and memory: Encrypted with keys derived from your passkey
- Platforms: Web and iPhone; Android "in the works"
Confer's prompts "are encrypted from your device directly into the TEE," and "the host never sees plaintext," per its private inference post.3
In Confer's words, "Confer cannot read your prompts or responses—not by policy, but by design."12 It says it uses "different open source models for different tasks" without naming them, and we found no public API.
Proton Lumo
- Where prompts are decrypted: Proton's Lumo GPU servers
- Who checks it: No attestation found
- History and memory: Saved history uses zero-access encryption; guest chats are erased after each session
- Platforms: Web, iOS and Android
Proton encrypts each prompt so "only the Lumo GPU servers are able to decrypt them."13 Its security post says that there, "the LLM gets to see the decrypted user message and process it directly."4
Proton says Lumo doesn't log or train on chats and runs on servers Proton controls. Lumo's code is open source, but its servers publish no attestation, so those commitments rest on policy, much like Venice's Private mode.
Duck.ai
- Where prompts are decrypted: The model provider, which receives your text without your identity
- Who checks it: No attestation shown to users
- History and memory: Recent chats saved on your device; optional encrypted Sync & Backup
- Platforms: Web and DuckDuckGo's browsers
DuckDuckGo removes your IP address and other identifying metadata, then calls the model provider itself, so requests "appear as though they are coming from DuckDuckGo."5 The provider still receives your prompt text, under agreements that bar training and require deletion after each reply, with listed exceptions.
Two of its ten models run in a trusted execution environment, and recent chats stay on your device by default.14
Where is Maple ahead, and where is Venice ahead?
Where Maple is ahead
- Every chat on every plan, Free included, is decrypted only inside attested enclaves. On Venice, only E2EE on Pro keeps prompts out of Venice's own servers.
- Maple's apps verify the enclave automatically at the start of every session. Venice's web app does so for E2EE sessions.
- The apps, the enclave service and Maple Proxy are open source under MIT, with a reproducible enclave build. We found no public source for Venice's apps or proxy.
- Web search works with every model, called from inside the enclave. Venice turns search off in E2EE.
- The desktop and mobile apps parse documents on your device. Venice doesn't support file uploads in E2EE.
- Chat history syncs across devices, encrypted with a key used only inside the enclave. Venice's stays on each device unless you restore a Pro backup.
- Native apps for macOS, Windows and Linux, a team plan, and an API proxy that verifies the enclave for you. We found no Venice desktop app or team plan.
- Maple's free plan allows 100 messages a day; Venice's allows 10 text prompts.
Where Venice is ahead
- About 140 text models, including Claude, GPT, Gemini and Grok.7
- Image, video and music generation, with daily image prompts on Free.1
- More uncensored models, on every plan including Free, and one that runs in E2EE.
- Lower prices: Pro is $18 a month, and yearly billing works by card.
- Memoria, a memory feature that works across chats. Maple has no cross-chat memory yet.
- In E2EE, Venice's web app verifies the model's own enclave. Maple users verify Maple's enclave, which verifies the model's.
- You can start without an account, sign in with a wallet and pay with crypto credits.9
Both say chats aren't used to train models.15 In both, the web-search provider receives the query text, and neither offers a BAA or has published a SOC 2 report.
Is there an uncensored alternative to Venice AI?
Yes, though none matches Venice's range. Most of Venice's uncensored text models run in Private mode; one Gemma 4 model also runs in E2EE.7
Both alternatives below are text only. An uncensored model reduces refusals; it doesn't guarantee an answer to every request.
DeepSeek V4.1 Flash Uncensored on Maple
- What it is: DeepSeek V4.1 Flash, abliterated to reduce refusals
- Where prompts are decrypted: Only inside its own attested enclave
- Plans: Pro, Max and Team, in beta; not Free
Abliteration finds the internal direction a model uses when it decides to refuse and removes it from the weights. It's meant for moments when a stock model balks at something legitimate, such as a frank medical question or dark fiction.
It's in the model picker on Pro, Max and Team. Like our other models, it runs in its own attested enclave, so Maple cannot see those chats either. Our guide to the abliterated DeepSeek V4.1 Flash explains how it was made, and our cybersecurity page covers it for security work.
Abliterated models on your own computer
The method traces back to research that found refusal is mediated by a single direction in each of the open models tested.16 People publish abliterated versions of many open models on Hugging Face, and Ollama and LM Studio can run them.
No company sees these prompts, but quality varies by publisher, and laptop-sized models are weaker than large hosted ones.
What is Maple?
Maple AI (maple.ai) is a private AI chat app from Maple Privacy Labs in Austin, Texas. We run open-weight AI models inside attested enclaves, so you can use capable models without hosting them, and Maple cannot see your chats.
Maple Chat offers eight open-weight models: GLM 5.3, GLM-5.3 Flash, Kimi K3, DeepSeek V4.1 Flash, DeepSeek V4.1 Flash Uncensored, GPT-OSS 120B, Gemma 4 31B and Llama 3.3 70B. Free includes GPT-OSS 120B and Llama 3.3 70B; Pro, Max and Team get the full list.
At the start of each session, the app checks the attestation's signature, its certificate chain to the AWS Nitro root and the enclave's code measurement against a Maple-approved list, and sends nothing if a check fails.
That works like certificate chains on the web: you check Maple's enclave, and Maple's enclave checks the model's. The proof page explains the chain, and the browser check runs the same verification your app does. We don't train on your conversations.
Maple includes web search on every plan. It runs through Kagi's search API, called from inside Maple's enclave, and Kagi receives the search query the model writes, not your account.
Chat history syncs across your devices, encrypted with a key used only inside the enclave. Maple Work, our desktop agent for Mac, Windows and Linux, is in early access on paid plans. It can hand a task to Claude Code or Codex signed in to your own account, and that hand-off goes to Anthropic or OpenAI, outside Maple's private path.
Apps are on the downloads page. Developers can use Maple Proxy, an OpenAI-compatible API that verifies the enclave for them, and organizations the team plan.
You still rely on the enclave hardware, the published code and Maple's signing key, and on Kagi for the search queries the model writes. We're working toward a SOC 2 audit and don't offer a BAA.
How much do Venice AI alternatives cost?
The table lists every published tier at web prices in US dollars.
| Product | Free | Main plan | Yearly | Higher tiers | Team | Bitcoin |
|---|---|---|---|---|---|---|
| Venice | 10 text and 15 image prompts a day1 | Pro $18/mo | $180/yr | Pro Plus $68/mo; Max $200/mo | None found | Yearly plans, through BTCPay |
| Maple | 100 messages a day, 2 models | Pro $20/mo | $216/yr, Bitcoin only (10% off) | Max $100/mo | $30/user/mo | Yearly Pro and Max |
| Confer | 20 messages a day, 5 saved chats | Membership $34.99/mo17 | None found | None | None found | None found |
| Proton Lumo | Guest and Free; limits not published | Plus $12.99/mo18 | $119.88/yr | None | Professional $14.99/user/mo19 | After free sign-up |
| Duck.ai | No account; limits not published | Plus $9.99/mo, with VPN20 | $99.99/yr | Pro $19.99/mo | None found | None found |
| Ollama, LM Studio | Free | None | None | None | None | Not needed |
Checked 31 Oct 2026, from each company's own pricing page. In-app prices on iPhone are often higher. Maple's plans are on Pricing.
Venice accepts Bitcoin through BTCPay on yearly plans.9 Maple's yearly billing is Bitcoin only, at 10% off, and excludes Team. Proton takes Bitcoin once you've created a free account.21
Is there a free alternative to Venice AI?
Yes. Every hosted app here has a free option, and local apps cost nothing beyond your hardware. Venice's free plan includes uncensored models and web search, but not its enclave modes.1
Maple's free plan runs in the same attested enclaves as the paid plans, though its uncensored model isn't included. For a free uncensored option with no company involved, run an abliterated model locally.
Can you run a Venice AI alternative on your own computer?
Yes. LM Studio and Ollama run open-weight models on your own computer at no cost. LM Studio says "none of your messages, chat histories, and documents are ever transmitted from your system" during local use.6 Ollama says, "We don't see your prompts or data when you run locally."22
The trade-offs are hardware and model size; LM Studio recommends 16GB or more of RAM.23
How do you choose a Venice AI alternative?
Choose by questions you can check on each company's own pages, not by the word "private" on a homepage.
| Question | What a checkable answer looks like | Where to look |
|---|---|---|
| Where is my prompt decrypted? | A named place: an attested enclave, the company's servers, a model provider, or your device | The security or privacy page |
| Who checks the enclave, and when? | The app verifies it automatically before sending, and you can run the check yourself | Attestation docs, a verify page, published source |
| Is the strongest mode the default? | It covers every model and plan, or you opt in | The pricing page and model list |
| What turns off in that mode? | Features that stop working, such as web search, memory or uploads | The mode's own documentation |
| What does it cost, and how can I pay? | Every tier, the free limit, and card, in-app or Bitcoin | The pricing page |
If you need frontier models, video or the widest uncensored catalog, Venice covers more than any alternative here. If you want privacy that's checked on every chat without choosing a mode, start with the first two rows. Maple, Confer and local apps answer them with an enclave or your own device; Lumo and Duck.ai, with policy and a proxy.
Sources
- Venice, Pricing. Plans, credits, uncensored models on every tier, NSFW image generation on Pro, and media generation.
- Venice, Privacy in Venice. The four privacy modes, the shared proxy and the E2EE verification icon.
- Confer, Private inference, January 5, 2026. Encryption into the TEE and attestation checked against a transparency log.
- Proton, Lumo security model. Decryption on Proton's servers and zero-access encrypted history.
- DuckDuckGo, How does Duck.ai protect my privacy?. Proxying, provider agreements, models and enclave-hosted models.
- Element Labs, LM Studio privacy policy. Local use.
- Venice, Venice API: text models. Text models by privacy mode, E2EE support and uncensored models.
- Venice, TEE and E2EE models. E2EE encryption and attestation.
- Venice, FAQs. E2EE limits, history, backups, accounts, credits and Bitcoin through BTCPay.
- Venice, Venice launches end-to-end encrypted AI, March 18, 2026. What TEE and E2EE each protect.
- Venice, Venice Memoria: technical overview, January 23, 2026. Where memories are stored and processed.
- Confer, Confer. In-app description: privacy design, history, plans, features and platforms.
- Proton, Lumo privacy. Prompt encryption, logging policy, training, models, open source code and guest mode.
- DuckDuckGo, Duck.ai Privacy Policy and Terms of Use. Local chat history and Sync & Backup.
- Venice, Terms of service, June 8, 2026. Section 10.2 on training.
- Andy Arditi and others, Refusal in language models is mediated by a single direction, 2024.
- Apple App Store, Confer Private AI. Membership price and platforms.
- Proton, Lumo pricing and plans.
- Proton, Lumo for business pricing.
- DuckDuckGo, DuckDuckGo's Pro plan, March 18, 2026. Plus and Pro plans, prices and the bundled VPN.
- Proton, Payment options. Bitcoin after account creation.
- Ollama, Privacy policy. Local use.
- Element Labs, LM Studio system requirements. RAM recommendation.
- Hugging Face, Models matching "abliterated". Community abliterated models.